Introduction: Installing Security Products Does Not Protect an Organization by Itself
- IDS: Intrusion Detection System
- IPS: Intrusion Prevention System
These systems monitor network traffic or system activity to identify signs of potentially malicious behavior. An IPS is intended to go a step further by taking preventive action, such as blocking traffic that matches a detection condition.
But the ability to detect an event is not the same as the ability to prevent damage. Traffic outside the monitoring scope remains invisible. An alert cannot change the situation unless someone has the responsibility and authority to respond. Even a well-chosen product may fail to perform as expected if its configuration, certificates, log collection, or detection rules are not properly maintained.
This article looks at the range of detection techniques available today, explains why AI/ML does not eliminate false positives or missed detections, and considers how organizations can build sustainable operations that connect detection to investigation, decisions, containment, and recovery. It also examines the responsibilities of executives and managers in making those operations workable.
Key points
- An IDS/IPS can inspect only the traffic and activity it is able to observe.
- Detection is the entry point to incident response. It must lead to investigation, decisions, containment, and recovery to help limit damage.
- AI/ML and additional monitoring products do not eliminate data gaps, false positives, missed detections, or the need for operational expertise.
- Management must provide the budget, people, decision-making authority, and practical priorities that allow teams to act.
1. What Do IDS and IPS Detect and Prevent?
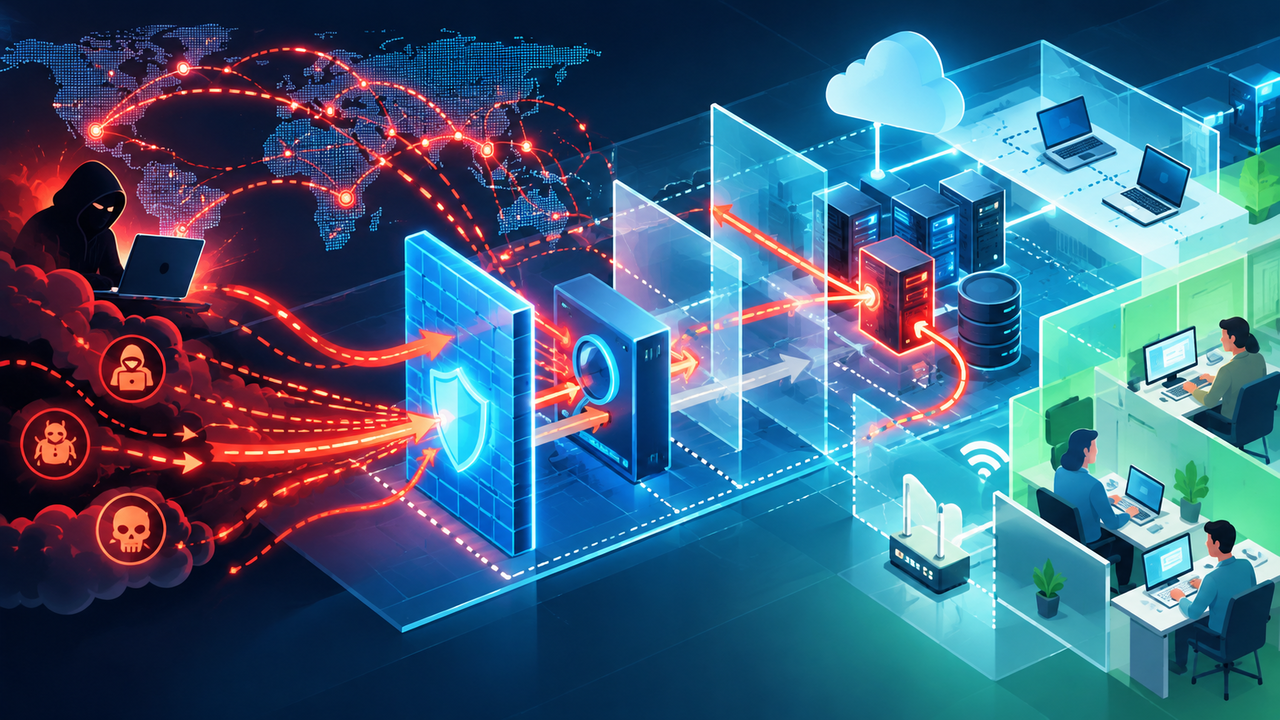
IDS/IPS is not a device that stops every attack. It is one layer of defense: it identifies suspicious signs in the traffic or activity it can monitor, may block activity when configured to do so, and records information that can support investigation.
| Function | What it does | Why it matters to the organization |
|---|---|---|
| IDS | Detects, records, and reports suspicious traffic or activity | Provides clues that can help the organization recognize an attack and begin investigating |
| IPS | Takes preventive action, such as blocking traffic that meets defined conditions | Can stop some matching attacks before they reach the protected system |
| Anomaly and behavior analysis | Examines traffic volume, destinations, usage patterns, and protocol deviations | Can provide leads on activity that does not match known attack patterns |
| Logs and alerts | Records detection details and notifies relevant people or systems | Supports incident response, audits, post-incident reviews, and improvements to detection rules |
IDS and IPS do not necessarily refer to separate products. A single product may provide both capabilities. They can also be deployed as network-based systems that inspect traffic in transit, or as host-based systems that monitor activity on individual servers and endpoints. For an IPS to block activity, it must be deployed in a position where it can control the relevant traffic, or have the ability to take preventive action on the host. Organizations should therefore verify a product’s placement, configuration, and enabled features rather than relying on its name alone. [1]
2. Detection Techniques Have Expanded, but Blind Spots Remain
Signature matching remains an important detection method. However, IDS/IPS has never relied exclusively on known attack patterns. Protocol anomaly detection and traffic behavior analysis have also been used for many years, and detection systems commonly combine multiple techniques. It is therefore inaccurate to divide detection into just two categories: “traditional signatures” and “new AI/ML.” [1]
| Detection or analysis method | How it works | Strengths and limitations |
|---|---|---|
| Signature matching | Compares activity with known attack patterns or characteristics | Can identify known threats relatively clearly, but may be less effective against unregistered or modified attacks |
| Protocol anomaly analysis | Detects behavior that deviates from protocol specifications or normal protocol use | Can identify malformed or unusual communications, but may struggle to judge abuse of otherwise valid procedures |
| Behavior and anomaly analysis | Detects deviations from normal patterns in traffic volume, destinations, usage times, access targets, and other activity | Can provide clues about unknown activity, but legitimate business changes may also appear anomalous |
| Log correlation | Links events from different systems by time or other relationships | Helps reconstruct a sequence of activity, but analysis is limited when logs are missing or inconsistent |
| Threat intelligence matching | Compares activity with publicly available or shared indicators such as malicious IP addresses, domains, and file hashes | Provides clues about known threats, but depends on the freshness of the information and changes in attacker infrastructure |
NDR, EDR, SIEM, and XDR are technology and product categories that support these forms of analysis across different observation points and information sources. Some products use machine learning or statistical analysis to detect anomalies that may be difficult to identify with a single signature. However, AI/ML has not completely replaced signature-based or rule-based detection.
AI/ML and behavior analysis can strengthen detection, but their effectiveness depends on the quality of the data and changes in the environment. Increasing the number of monitored sources does not automatically make detection more accurate. Organizations must continuously tune what they collect, what they consider normal, and which changes should be treated as significant signals in their particular environment. [3][4]
3. Why AI/ML Does Not Eliminate Missed Detections or False Positives
1. “Low-and-Slow” Activity Blends into Normal Operations
An attacker who exfiltrates a large amount of data in a short period may trigger an alert because of a sudden increase in traffic. One alternative is to spread the activity over a longer period, collecting and sending smaller amounts of data at a rate close to ordinary usage. This kind of activity is commonly described as “low and slow.”
Each individual communication may look unremarkable, making the activity difficult to detect with simple thresholds. However, correlating a user’s behavior, destinations, and data access over a longer period may reveal suspicious patterns. The important point is to analyze activity across time and systems rather than relying only on isolated alerts. [3]
2. Abuse of Legitimate Credentials and Permissions
When attackers use stolen passwords, session tokens, or API keys, their communications may appear to originate from legitimate users or systems.
Successful authentication does not prove that a user is authorized to view or modify the data in question. Organizations need to examine identity activity, permissions, accessed resources, and the business context of operations, rather than relying on network monitoring alone. Understanding a user’s role and normal responsibilities is also important when determining whether an operation is unusual. [2]
3. The Definition of “Normal” May Already Be Wrong
Behavior analysis may compare current network traffic and user activity with a baseline representing normal conditions. But if a system has already been compromised when that baseline is created, malicious activity may be learned as part of normal behavior.
The UK’s National Cyber Security Centre (NCSC) advises organizations to consider whether a system may already be compromised when establishing a baseline. Baseline comparison can be useful, but the baseline should not be trusted unconditionally. [3]
4. False Positives, False Negatives, and Alert Fatigue
Increasing the sensitivity of anomaly detection may cause routine business changes, development tests, and overnight batch jobs to generate alerts. Conversely, making detection conditions too strict in an effort to reduce false positives may cause genuine signs of an attack to be missed.
- False positive: An alert identifies activity as anomalous or malicious when there is no actual problem.
- False negative: A real problem occurs, but the detection system fails to identify it and raises no alert.
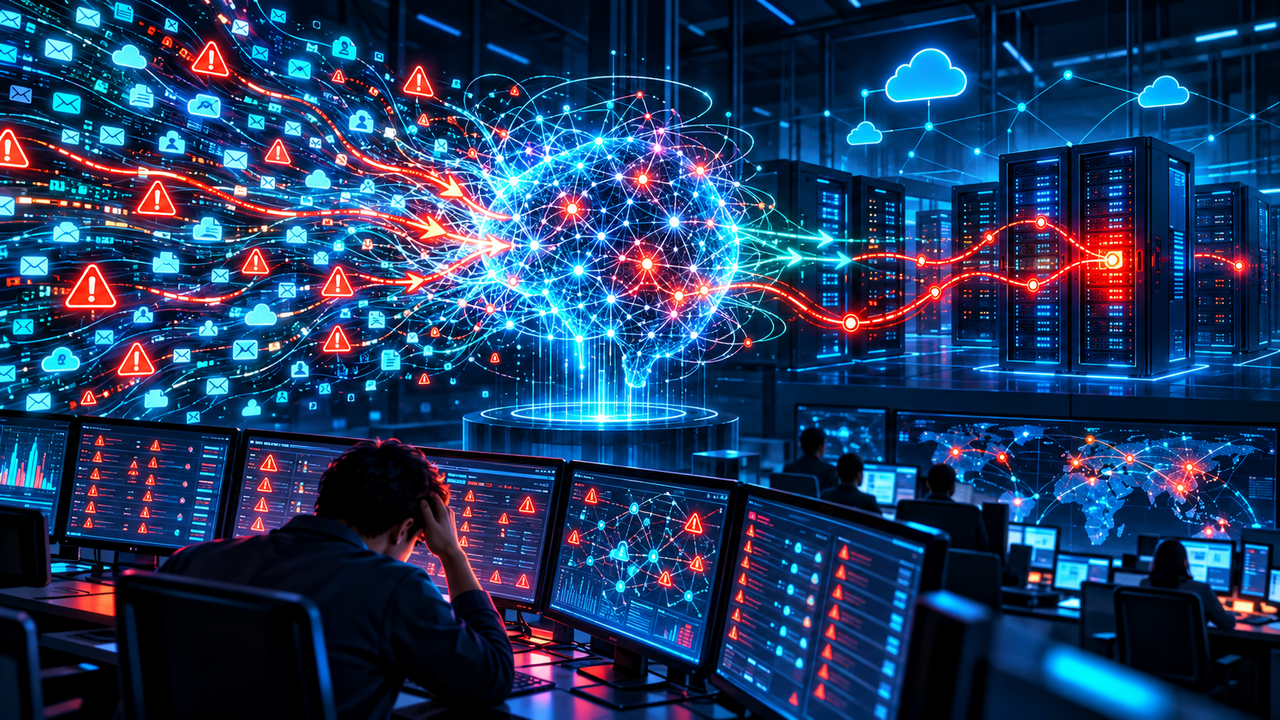
Guidance on implementing SIEM and SOAR platforms published by Australia’s national cybersecurity authorities in 2025 explains that false negatives can result from incomplete or inconsistent logs and poorly tuned detection rules. False positives can become widespread when excessive data is collected without appropriate tuning of rules and filters. Too many false positives can overwhelm analysts and delay responses to real incidents, leading to “alert fatigue.” [4]
                    The Alert Fatigue Cycle

       Excessive log collection and poorly tuned detection rules
                              |
                              v
                  Large volumes of alerts,
                  including false positives
                              |
                              v
                    Growing analyst workload
                              |
                              v
                 Triage and investigation become
                       increasingly mechanical
                              |
                              v
                  Important signals are missed
                       or handled too late
                              |
                              v
                 Greater damage and recovery costs
                              |
                              +------> Further operational fatigue
AI does not automatically solve this problem. NCSC recommends keeping alert volumes at a level that analysts can investigate, correlating multiple signals, reviewing detection rules regularly, and validating detection effectiveness through exercises and other testing. [3]
4. Design the Detection-to-Response Process Before Adding More Expensive Products
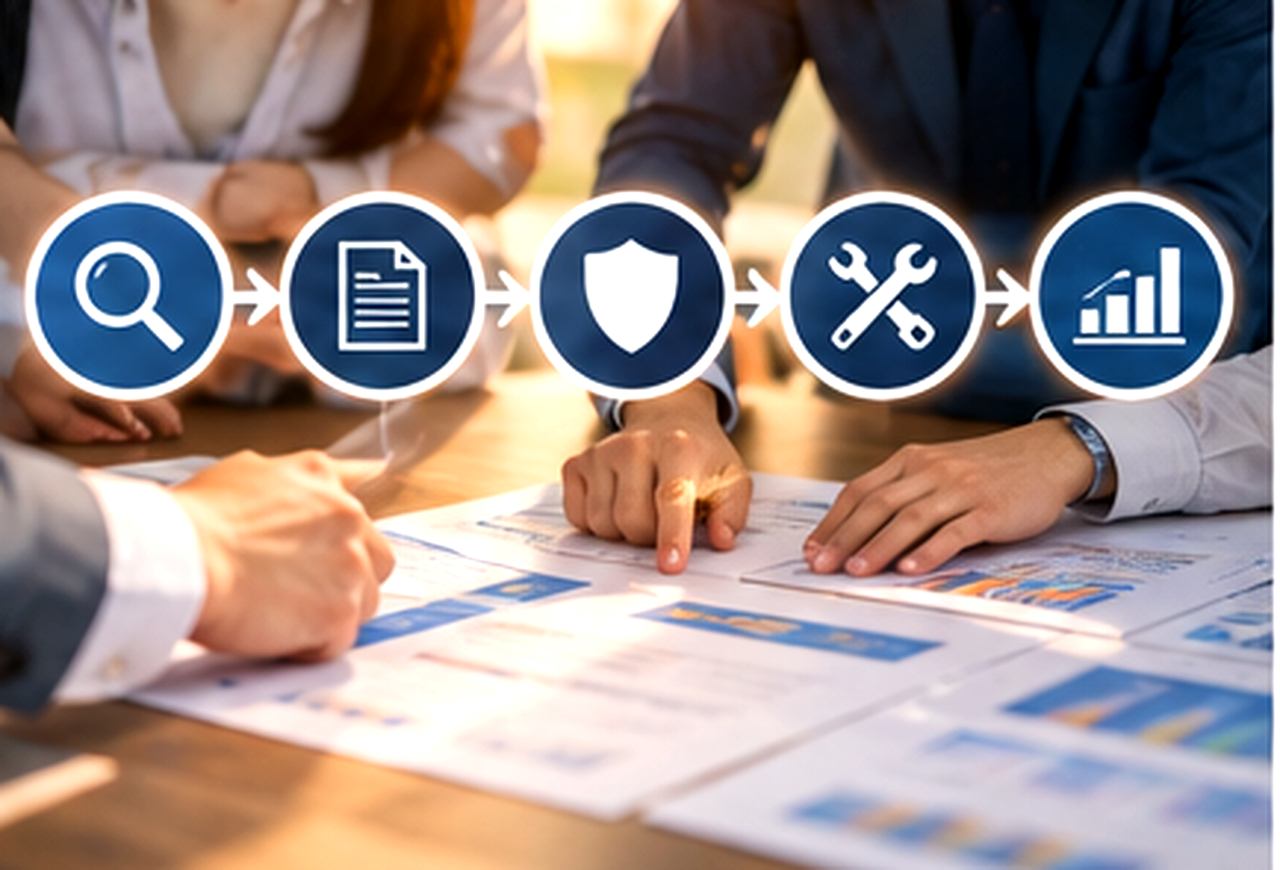
IDS/IPS, NDR, EDR, and SIEM each capture or process different types of information. The goal is not to deploy every available product. It is to build a system in which the information needed to protect the organization’s important assets against its relevant threats is collected, assessed, and translated into decisions and action.
       Network, endpoint, identity, cloud, and application information
                              |
                              v
                    +------------------+
                    | Detection and    |
                    | analysis         |
                    | Rules / correlation |
                    +------------------+
                              |
                              v
                    +------------------+
                    | Triage           |
                    | Severity / scope |
                    +------------------+
                              |
                              v
                    +------------------+
                    | Investigation    |
                    | and decisions    |
                    | Verification /   |
                    | authorization    |
                    +------------------+
                              |
                              v
                    +------------------+
                    | Containment and  |
                    | recovery         |
                    | Isolation /      |
                    | blocking /       |
                    | restoration      |
                    +------------------+
                              |
                              v
                    +------------------+
                    | Review and       |
                    | improvement      |
                    | Updated rules    |
                    | and procedures   |
                    +------------------+
                              |
                              +--------> Feed improvements back into
                                         detection and analysis
Detection and response should be designed as one connected process. Ownership, decision criteria, and handoff conditions should be clear at every stage.
| Operational practice | What it involves | Expected benefit |
|---|---|---|
| Prioritize assets by importance | Identify systems that handle personal or payment data, critical APIs, administrative environments, and other important assets | Concentrate monitoring and response resources where they matter most |
| Establish logging and monitoring coverage | Select the necessary network, endpoint, identity, cloud, and application logs; regularly check collection status and gaps | Reduce blind spots and shortages of information needed for analysis |
| Choose SIEM data sources deliberately | Prioritize logs needed for security analysis, and consider separating them from large datasets collected mainly for retention or audit purposes | Control unnecessary data volume and cost while maintaining analytical value |
| Triage alerts | Prioritize by severity, affected assets, attack progression, and potential business impact | Investigate the most important alerts first and reduce response delays |
| Tune detection rules continuously | Review false positives and false negatives; add, revise, or retire rules | Keep detection aligned with changes in the environment and threat landscape |
| Define response procedures and authority | Specify who investigates and who can disable accounts, isolate endpoints, block network traffic, or take services offline | Shorten the time from detection to containment |
| Introduce automation gradually | Start with repeatable actions that have clear conditions; prepare ways to reverse mistakes and restore service | Reduce manual workload while limiting disruption caused by incorrect automated actions |
| Conduct exercises and post-incident reviews | Practice alert handling, communication, containment, and recovery; also test detection rules | Identify procedural weaknesses and unclear areas of responsibility |
Collecting more logs does not necessarily improve analytical accuracy. A SIEM needs to select logs that are meaningful for identifying security events and analyze them with appropriate rules and filters. The Australian guidance also warns about the cost and analytical inefficiency of using a SIEM merely as a repository for every available log. [4]
Automation is not a universal solution either. An incorrect decision that automatically isolates a legitimate user’s account or a business-critical system can create an operational outage separate from the security incident itself. SOAR and similar automated response capabilities must be designed and maintained for the organization’s actual environment. The Australian guidance recommends that organizations whose SIEM analytics and operational experience are not yet mature should first strengthen log analysis and detection operations rather than rushing into SOAR deployment. [4]
Incident response plans, roles, decision-making authority, procedures, and exercises must be established separately from the deployment of detection products. NIST SP 800-61 Rev. 3 likewise frames incident response as part of organization-wide cybersecurity risk management, rather than as a collection of isolated technical tasks. [5]
5. The Responsibilities of Executives and Managers
Even advanced IDS/IPS and AI systems cannot deliver their expected value if the organization lacks the people, decision-making authority, time, and budget to operate them. Security should not depend solely on the extra effort of frontline engineers. Management must create the conditions for sustainable operations.
| Management responsibility | What management should do | What to avoid |
|---|---|---|
| Set priorities and make trade-offs | Set response priorities, deadlines, and budgets based on critical assets and business impact | Treat everything as the top priority and demand additional controls without changing existing workloads or delivery dates |
| Establish response authority | Assign accountable decision-makers who can authorize network isolation, account suspension, or service shutdown during an emergency | Hold technical staff responsible without giving them the authority needed to act |
| Provide staffing and expertise | Secure training, backup personnel, external specialists, or managed services where needed | Concentrate monitoring, investigation, and response knowledge and workload in one individual |
| Build a culture that learns from failure | Review incidents and missed detections in terms of systems, procedures, and information sharing as well as individual actions | Blame people who report problems and create incentives to hide issues |
| Protect frontline teams through coordination | Reconcile requests from customers, sales, and auditors against risk assessments, and provide a realistic roadmap | Pass contradictory demands and excessive pressure directly to the people doing the work |
Deciding What Not to Do Is Also a Management Responsibility
Expanding security controls and monitoring coverage takes time for design, development, testing, and operations. It is not realistic to impose every additional requirement on frontline teams while leaving deadlines and delivery expectations completely unchanged.
When introducing new monitoring or response processes, management must decide which existing functions or tasks should be deprioritized and which schedules need to change. Rather than simply telling teams to “find a way,” the organization must take responsibility for the trade-offs involved.
Measure the Quality of Response, Not the Number of Alerts
The number of alerts detected is not, by itself, an appropriate measure of a security team’s performance. Generating more alerts does not necessarily make an organization safer.
Executives and managers should use a combination of indicators to understand whether detection and response are working in practice.
| Metric | Example definition | What to consider when interpreting it |
|---|---|---|
| MTTD (Mean Time to Detect) | Time from the start of suspicious activity to its detection by the organization | The actual start of an attack may not be known precisely, so define the measurement starting point |
| MTTA (Mean Time to Acknowledge) | Time from an alert being generated to a team member acknowledging or accepting it | Specify whether acknowledgement, review, or the start of investigation marks the beginning of response |
| MTTC (Mean Time to Contain) | Time from detection to containment | Avoid simplistic comparisons across incidents with different severity and response requirements |
| Recovery time | Time required to restore a system or business service to an acceptable state | Measure containment and recovery separately |
| False-positive and missed-detection trends | Rules that generate many unnecessary alerts, and signals that exercises or post-incident reviews show were missed | Consider investigation quality and monitoring coverage, not just alert counts |
| Monitoring coverage | The proportion of important assets whose logs or traffic are actually collected and analyzed | Distinguish between data being collected and data being analyzed effectively |
The abbreviation MTTR is used in different contexts to mean Mean Time to Respond, Resolve, or Recover. Organizations should define the start and end points of the metric they use and avoid confusing response, containment, and recovery times.
Focusing only on numerical targets can obscure investigation quality and differences in incident severity. Metrics should not be used to punish frontline teams. They should help identify weaknesses in operations and inform decisions about staffing and improvement investments.
Conclusion: Sustainable Operations Matter More Than Product Sophistication
IDS/IPS remains an important defensive capability for detecting and blocking suspicious network traffic and known attack patterns. When used appropriately, NDR, EDR, SIEM, and AI/ML-based analysis can extend an organization’s visibility and detection capabilities.
However, newer products alone cannot resolve the challenges posed by encrypted traffic, misuse of legitimate credentials, attacks concealed within trusted software or communications, lateral movement inside networks, or failures to act after detection. Organizations must continuously verify that monitoring systems are functioning, required information is being collected, alerts are being handled appropriately, and damage can be limited if an intrusion occurs.
The responsibility of executives and managers is not simply to purchase the latest security products. They must understand the assets that need protection and the business risks involved, provide the necessary budget and people, grant appropriate decision-making authority, and establish priorities and operating structures that frontline teams can actually carry out. Engineers, in turn, need to explain not only what their technology can detect or prevent, but also what remains outside its field of view and what action the organization needs to take.
An IDS/IPS is not a device that protects an organization simply because it has been installed. It delivers value when the organization keeps monitoring effective, turns alerts into action, and continuously reviews and improves its weaknesses.
References
- NIST SP 800-94, “Guide to Intrusion Detection and Prevention Systems (IDPS)” (February 2007). Foundational material on network-based, wireless, network behavior analysis, and host-based IDPS, as well as design, deployment, configuration, monitoring, and maintenance. Because it is an older publication, it is used here for basic technical classifications rather than as a comprehensive description of current products. NIST CSRC
- CISA, “AA20-352A: Advanced Persistent Threat Compromise of Government Agencies, Critical Infrastructure, and Private Sector Organizations” (December 17, 2020). Describes the SolarWinds Orion supply chain compromise, the malicious DLL signed with a legitimate code-signing certificate, and communications designed to resemble legitimate Orion traffic. CISA Advisory
- UK National Cyber Security Centre, “Building a Security Operations Centre (SOC)—Detection Practices.” Guidance on the limitations of baselines, correlation across multiple logs, alert triage, handling false positives, continuous review of detection rules, and validation through exercises. NCSC
- Australian Signals Directorate / Australian Cyber Security Centre, “Implementing SIEM and SOAR Platforms: Practitioner Guidance” (May 27, 2025). Practical guidance on SIEM log selection and analysis, false positives and false negatives, alert fatigue, risks associated with automated SOAR responses, staffing, and continuous tuning. Australian Cyber Security Centre
- NIST SP 800-61 Rev. 3, “Incident Response Recommendations and Considerations for Cybersecurity Risk Management: A CSF 2.0 Community Profile” (April 3, 2025). Recommendations for integrating incident response into organization-wide cybersecurity risk management. NIST CSRC
This article does not dismiss the value of IDS/IPS or monitoring products that use AI. Detection coverage and response capabilities vary by product, deployment, configuration, and monitored environment. Always assess the actual architecture and operational conditions before deployment.